Make the early implementation decisions explicit: the job, permitted actions and ongoing responsibilities. Test how they work alongside capability, source data, cost and business value before allowing live consequences.
What you'll learn
- How to turn a broad ambition into a testable initial job
- Why a written policy needs implemented and tested controls
- What operating owners and backups need before handover
- How to review planning gaps alongside technical feasibility and value
Before live access, agree the job, permitted actions and operating responsibilities. Turn them into examples, actual permissions, tests and a handover that the process owner and maintainer can use.
Before an AI agent receives live access, agree the job it should complete, the actions it may take and who will look after it. Turn those decisions into examples, permissions, tests and an operating arrangement. Review technical capability, source data, cost and business value alongside them.
The practical mistakes below concern those early choices. They are useful questions for your project, not a ranking of why most agent projects fail. A clear planning document helps the builder and process owner decide what to implement and which work must remain with people.
Why can starting too wide make implementation harder?
A broad label can hide different jobs with different information, approvals and exceptions. Break “handle client communication” into specific requests and results before estimating the work. Choose an initial task that the business can judge and test; narrow scope alone does not guarantee a useful or safe result. Anthropic’s December 2024 agent-building guide recommends starting with the simplest solution that meets the need and adding complexity when it is justified.[1]
For example, answering a delivery-status question differs from negotiating a discount or changing a contractual commitment. They may arrive in the same inbox but need different sources and authority. Listing them separately makes it easier to decide what the first workflow includes and where excluded requests go.
Write the allowed job and its exceptions before granting access. An example that shows a correct reply should also say who receives it, what sources may be used and when the agent must stop or ask a person.
Apply that to the job as well as the technology. If an ordinary rule or a draft for review solves the problem, explain why a more independent agent would add value before widening the project.
A hypothetical first task might prepare a follow-up draft after an agreed interval, using a specified proposal record and recipient. The interval is a business choice, not the definition of the whole job. Include replies, cancellations, missing records and duplicate triggers when you decide what the task should do.
What happens when action controls are left undecided?
The builder cannot reliably implement the business’s authority rules if nobody has decided them. List the actions the job needs, the source and destination for each and which ones require an authorised decision. Then verify the actual permissions and the path that performs the action.
An instruction explains intended behaviour; access restrictions and approval checks need to enforce the relevant boundary. A product setting can help implement it. Test the setting against the exact action you need to hold rather than assuming that a review notification also blocks execution.
Say an agent proposes to mark a deal closed before a client has confirmed. Decide which confirmation is required, who may approve the change and what happens if the reviewer is absent. A good draft summary does not answer those authorisation questions.
Record what happens on refusal, changed proposals, expiry and failed connections. If a consequential action needs prior approval, missing approval must not turn into permission. Keep the held work visible to a named person and provide a manual route for urgent cases.
Why is launch not the finish line?
The workflow needs someone to judge results, arrange repairs and decide what changes when the business changes. Name those responsibilities before the launch team steps away. A supplier can retain technical support while the business owns process decisions; make the split and backup arrangements explicit.
Scope, action controls and operating responsibility deserve the same attention as technical capability.
For example, a new offer can require revised instructions, a connected tool can change a record format and an unfamiliar request can need human handling. Plan how each reaches the right person. Do not assume every tool change causes a silent failure or that a calendar review will discover every error.
Set the review routine from consequences, change rate and actual workload. Include the time people spend checking, correcting and resolving exceptions in the operating estimate. Make sure a serious problem can reach someone between scheduled reviews.
How can the planning mistakes combine in practice?
Consider a hypothetical team that asks for “all customer follow-up”, grants a shared account and leaves ongoing decisions with whoever has time. A new service request reaches the workflow. The agent has no agreed rule for it, and the staff cannot tell who may expand the job or stop the affected action.
Those gaps can coexist, but one does not prove the others exist. Investigate the actual scope, permissions and response route rather than assuming a standard failure sequence or a particular month when problems appear. The technical behaviour and source records may need correction too.
To recover, identify affected work and hold consequential actions where needed. Assign the missing decision, test the corrected rule and inspect earlier work that may need repair. Record the manual process the team will use meanwhile. Compare that effort with the value of continuing the workflow rather than treating launch as an obligation.
Prevent the same uncertainty at the next change by documenting what was approved, who can revise it and how tests will show the intended result. Keep ordinary cases and important exclusions available to the person accepting the change.
What should you do instead of repeating the mistakes?
Use the table as a planning review with the process owner and builder. Each row needs an explicit decision and evidence that the implementation matches it. The list complements checks of capability, data, dependencies, cost and applicable obligations; it is not a complete readiness certificate.
| Planning mistake | What becomes unclear | What to decide and verify |
|---|---|---|
| Starting too wide | Eligible requests, sources, results and exceptions | Define a bounded initial job, representative examples and a route for excluded work |
| Leaving controls undecided | Which actions may run and who authorises changes | Assign permissions and approvals, then test allowed and prohibited actions |
| Treating launch as done | Who judges output, repairs defects and handles changes | Name operating roles, backups, review and response arrangements before handover |
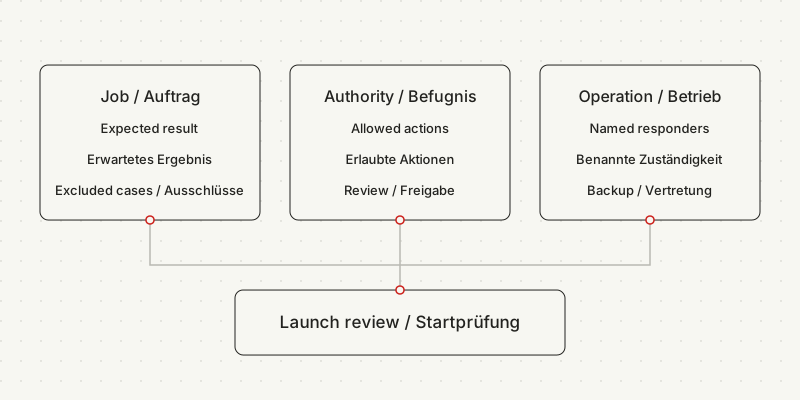
Have the operator show a normal task, an excluded request and a failed handoff using the proposed arrangement. The builder should explain how the configured permissions and approval route match the agreed decisions. Turn a missing answer into assigned work rather than a reassuring acceptance statement.
Keep the decision record proportionate and usable. It may be a shared page with links to test examples and access settings. Its value comes from the people who can use it and the controls that implement it, rather than its length or a framework name.
Which three decisions should you make before the build begins?
Agree the first job, the authority needed for its actions and the operating responsibilities with the people who can decide them. Use early tests to resolve unknowns and revise the scope before allowing consequential live work. The questions below can start that discussion; they do not impose a fixed meeting length or sample size.
Agree on the failures that would stop this workflow before choosing a launch date. Use the evaluation examples and sample-size boundaries to plan the initial tests, then add your own exceptional requests and check the saved business result.
Define the workflow narrowly enough to test
Describe representative inputs and the expected result, including missing information, duplicates and requests outside scope. If the team disagrees about correct handling, resolve the business rule or keep that case with a person before asking the builder to automate it.
Agree action rules and test their enforcement
List reads, writes, sends and handoffs. Identify required prior decisions, eligible recipients and access limits. The policy records what the business authorises; configured restrictions and execution checks must implement it. Test refusal and unavailable review as well as approval.
Name operating owners and backups before launch
Assign who judges results, maintains connections, receives provider notices and resolves exceptions. Agree response availability, scheduled and change-triggered reviews, and the manual alternative. Confirm the new owner can carry out the routine during handover.
Estimate the work after identifying the people, evidence and unresolved dependencies. Some decisions can be made quickly; access reviews or unclear process rules may need further work. Record those dependencies in the plan instead of promising that every project can settle them in a short workshop.
For the full phase sequence, see what a real AI agent implementation involves. The separate prototype-to-production guide owns the comparison between demonstrated capability and evidence for live operation.
Frequently asked questions
What is the most common mistake when implementing AI agents?
A useful first check is whether the job is specific enough to test. A label such as client communication can include requests with different sources, permissions and consequences. Define an initial task and excluded cases, alongside checks of capability, data, value and cost.
Why do most AI agent implementations never reach production?
Check the actual task, source information, technical ability, connections, action authority and operating arrangements. Broad scope, undecided controls and missing ownership can contribute to a stall, but they do not explain every project or make a universal failure ranking.
What is a control layer in an AI agent system?
It implements allowed actions, access restrictions, approvals and referrals. A written rule describes the intended authority; settings and execution checks must enforce the relevant boundary. Test refusal, changed proposals and unavailable review as well as a successful approval.
Who should be responsible for an AI agent system after launch?
Assign a process owner to judge results and business changes and a maintainer for technical repairs, with backups and response arrangements. These may be different people. If the role is missing after launch, assign it now and hold affected consequential work while unresolved decisions are made.
Notes
Source accessed 15 October 2026. The three planning decisions, review table and scenarios are practical recommendations, not measured failure rankings, guaranteed prevention or fixed workshop estimates.
- Building effective agents. Anthropic; 19 December2024, living page subsequently revised.
- Demystifying evals for AI agents. Anthropic; 9 January 2026; accessed 15 October 2026.