
Keep the project operating after the launch team leaves. Use a ninety-day review to check who judges the work, approves changes, arranges repairs and handles exceptions.
What you'll learn
- How to distinguish launch acceptance from ongoing responsibility
- What an owner, maintainer and backup need to agree
- How to route defects, changed business rules and out-of-scope requests
- What to demonstrate before the launch team steps away
Imagine this handover: an AI agent has been live for three months, and a customer asks why a reply still describes an old service. The workflow has an uptime dashboard but no person responsible for changing its instructions. The project was handed over as a finished installation; the ongoing job was never assigned.
Use the ninety-day point as a review milestone, not a predicted failure date. At that review, ask who can judge the work, who can repair it and who can stop it. A project can stall whenever those responsibilities fall between the supplier and the business.
What do the first ninety days look like?
Treat the first ninety days as an opportunity to prove that the business can operate the workflow after the launch team leaves. The test is whether ordinary work, exceptions and changes reach someone who can make a decision. A successful demonstration at launch does not settle those operating responsibilities. McKinsey’s May 2024 survey reported one to four months as the most common time to put generative-AI capabilities into production, varying by function and customisation.[3] This is broader generative-AI timing, not a measurement of agent failures.
Make the review specific. Ask the process owner to bring a completed task, a corrected task and an unresolved exception. Ask the maintainer to show where each went and how an affected action would be paused. If nobody can retrieve these examples, agree how they will be recorded before expanding the workload.
There is a useful distinction between technical delivery and continued usefulness. In its account of building a research agent system, Anthropic describes adding production tracing to diagnose failures and coordinating updates to avoid disrupting agents already running.[1] That is an example of continued engineering responsibility, not evidence that every business project fails on the same date.
What changes the day after go-live?
The business needs an operating agreement that still works when the launch team is unavailable. A supplier may remain responsible for technical support, or the business may take over. In either case, write down who decides whether the results are acceptable and who deals with a problem between scheduled reviews.
Separate acceptance from support. Signing off a working example does not tell the account manager where to send an incorrect customer reply. A support email address does not tell the supplier whether a newly introduced service belongs in the agent's scope. Both sides need a person who can answer those questions.
Before the launch team steps away, name the person who can accept the work, request a repair and pause an affected action.
Walk through an absence as well as a normal working day. If the main owner is away, the backup should know where the instructions, outstanding issues and manual process are kept. If support only covers agreed hours, decide what happens to unattended work outside them.
How do agents degrade without active ownership?
A change becomes an operating problem when nobody evaluates its effect or assigns a response. The owner does not need to repair every connection personally. They need to recognise that the work has changed, route the issue to the right person and decide what may continue meanwhile.
Make the handover actionable: who receives a problem, who decides its urgency, who can stop the affected action and who confirms that the repair worked? Write down the backup as well as the main owner.
The maintenance guide explains outdated instructions, changed connections and unfamiliar requests in detail. Use that routine to check the work; use the ownership agreement to ensure its findings lead to a decision.
Keep limitations separate from defects. A request outside the agreed job may need a human response rather than a repair. The guide to what agents are bad at helps frame that discussion. A problem connecting to a business system may instead need the technical maintainer. Give the operator a route for both.
A useful issue record names the affected outcome, an example, what is paused, the responsible person and the next decision. Avoid leaving a serious issue marked only as “AI quality”: the owner needs to know which customer, record or action may be affected.
What does the ninety-day cliff look like in practice?
The following are hypothetical handover failures. They show what to ask at a review, rather than reporting measured client results or a standard failure timeline. In each example, the agent may continue running while the team loses confidence in the work.
An agency stops trusting its drafts. Suppose an agent drafts client status emails. The account team begins rewriting recurring passages but sends no feedback because nobody owns the review. At the milestone, ask for examples of accepted and corrected drafts. Assign someone to distinguish missing project information from a changed writing rule, and decide which drafts still need approval.
A consulting firm's records stop matching its process. Imagine that a CRM field changes while the agent continues handling meeting notes. The team notices missing information in a report. Name the person who will inspect the destination records, identify the affected work and agree a repair. Keep the manual process available until the corrected route has been tested.
A founder changes the service offer. Say a business adds a new service while the agent still follows the original brief. Someone must decide whether the service belongs in the agent's job, what information it needs and whether replies require review. Without that decision, asking the maintainer to “update the AI” leaves the actual business rule unresolved.
The recovery question is the same: which work is affected, who will decide the response, and what will the team use while it is repaired? You can assign ownership after launch too. Do it before continuing a consequential action whose outcome is uncertain.
What does active ownership actually require?
Active ownership means making decisions about correct work, exceptions and changes, with a maintainer available for the technical tasks. Start with a clearly bounded single workflow, and record the responsibilities for that workflow rather than assigning an undefined duty to “look after AI”.
The process owner should be able to explain what a good result looks like and which actions need approval. The maintainer should know the agreed instructions, connected systems and safe way to test a repair. The operator should know where to report a problem and how to use the manual alternative.
| Ownership state | What it looks like | What to resolve at the review |
|---|---|---|
| Named owner and defined routine | A person reviews outcomes, makes scope decisions and assigns repairs | Confirm backup, response arrangements and outstanding changes |
| Informal ownership by the team | People correct work but cannot say who decides the next action | Name the decision-maker and a reachable route for issues |
| No assigned owner | The workflow runs while complaints wait or work moves back to people | Limit affected automatic work, assign responsibility and restore the manual route |
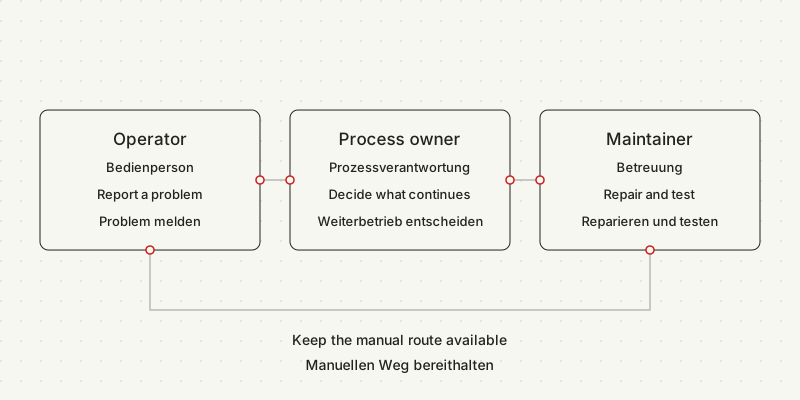
Do not size the role from a universal maintenance allowance. Observe the time spent on reviews, exceptions, repairs and change decisions. The volume and consequences of the job determine the commitment; a small launch project can still require a prompt response to a serious error.
How do you prevent the cliff before launch?
Before launch, agree the owner, backup, review schedule and change route, then demonstrate them in the handover. The aim is that someone outside the build can operate the agreed workflow and get help. If the workflow is already live, use the same sequence to close the gap now.
Keep the detailed maintenance checks in the linked guide. The handover should identify where that routine lives, who will run it and how findings become assigned work. Schedule the first review while the launch team is still available to explain unfamiliar behaviour.
Document the exception log and known edge cases
List excluded request types, exceptions seen during testing and the manual response for each. Show the new owner how to find an unresolved case and tell whether anyone has accepted it. Record who can approve an expansion of the agent's job.
Establish the review checklist
Agree where completed work, corrections, destination records and open issues can be inspected. Have the new owner carry out a review while the builder watches. Turn an unclear instruction into an assigned correction rather than assuming it will be understood later.
Set the review calendar before launch day
Put the initial review and the following checkpoints in the calendar, with owner and backup. Set the spacing from the workflow's consequences and change rate. Agree how urgent issues reach a person between appointments.
Define the update trigger
Name the business changes that need review before the agent uses them: a new service, recipient, approval rule or connected system. Agree who authorises the change, who tests it and who confirms the result. Keep a way to restore the previous working version.
Ask for a demonstration of a repair, including a test of previously working tasks. Anthropic's evaluation guidance describes turning reported failures into tests and maintaining those tests with clear ownership.[2] Apply that principle to your own workflow: the person accepting a repair should know which business result was checked.
Finish the handover with open decisions assigned, rather than hidden inside a general acceptance statement. That gives the business a way to keep the workflow useful after the excitement of launch has passed.
Frequently asked questions
Why do most AI agent projects stall after ninety days?
A project can stall when responsibility for decisions, repairs and exceptions disappears after launch. Use ninety days as a review milestone rather than a universal failure date. Name the process owner, technical maintainer and backup, and demonstrate how a problem reaches them.
What is prompt drift in an AI agent?
Prompt drift describes instructions that no longer match the business process. For the detailed failure modes and review routine, see AI agent maintenance. In the handover, assign who receives a changed business rule and who approves its use.
How do you prevent an AI agent project from stalling?
Agree a named owner, backup, review schedule, repair route and manual alternative. Demonstrate these during handover, including how an affected action is paused. If the agent is already live, assign the responsibilities now rather than waiting for the next review milestone.
What is integration drift in an AI agent?
Integration drift means a connected system changes in a way that affects the agent’s work. The maintenance guide covers detection and repair. The handover should name who receives provider notices, arranges the test and confirms the destination result.
Notes
Sources accessed 15 October 2026. Handover examples are hypothetical. Ninety days is a suggested review milestone, not a measured industry failure deadline. The provider case supports ongoing operating work, not a population failure claim.
- How we built our multi-agent research system. Anthropic; 13 June 2025.
- Demystifying evals for AI agents. Anthropic; 9 January 2026.
- The state of AI in early 2024: Gen AI adoption spikes and starts to generate value. McKinsey & Company; 30 May 2024; accessed 15 October 2026.
